carve-lora
CARVE - verified surgical removal of one capability from an entangled LoRA adapter (git revert for model capabilities).
CARVE — Contrastive Adapter Rotation for Verified Erasure
git revert for model capabilities. Post-hoc surgical removal of one capability from an entangled monolithic LoRA — without full retraining — with GATE held-out verification.
Project status (2026-07-17)
Overall: ~95% of stated proof goals. Core claim proven on Syn-2Cap (incl. full MLP), stronger holdout, Founder OS probe-path E2E, and TOFU-mini (with caveats below). Remaining: production Founder adapter, full TOFU/WMDP paper tables, multi-seed, 7B.
| Phase | Status | Done |
|---|---|---|
| A Infrastructure | Done | 100% |
| B Syn-2Cap | Done | 100% |
| C CARVE + Gate C | PASS (gate_proj + full MLP) | 98% |
| D Repair + GATE | Soft-cut + retain repair validated on MLP | 90% |
| E Ablations + figures | Done | 95% |
| F Founder OS | Sample-trace E2E PASS (proxy adapter) | 70% |
| G TOFU mini | PASS (weak pre-retain — see caveats) | 60% |
| H Paper + OSS | Updated with complete proof | 90% |
Claim proven
Interconnected capabilities inside one LoRA can be removed post-hoc without full retraining, when contrastive inner-space stats are linearly separable and GATE holds.
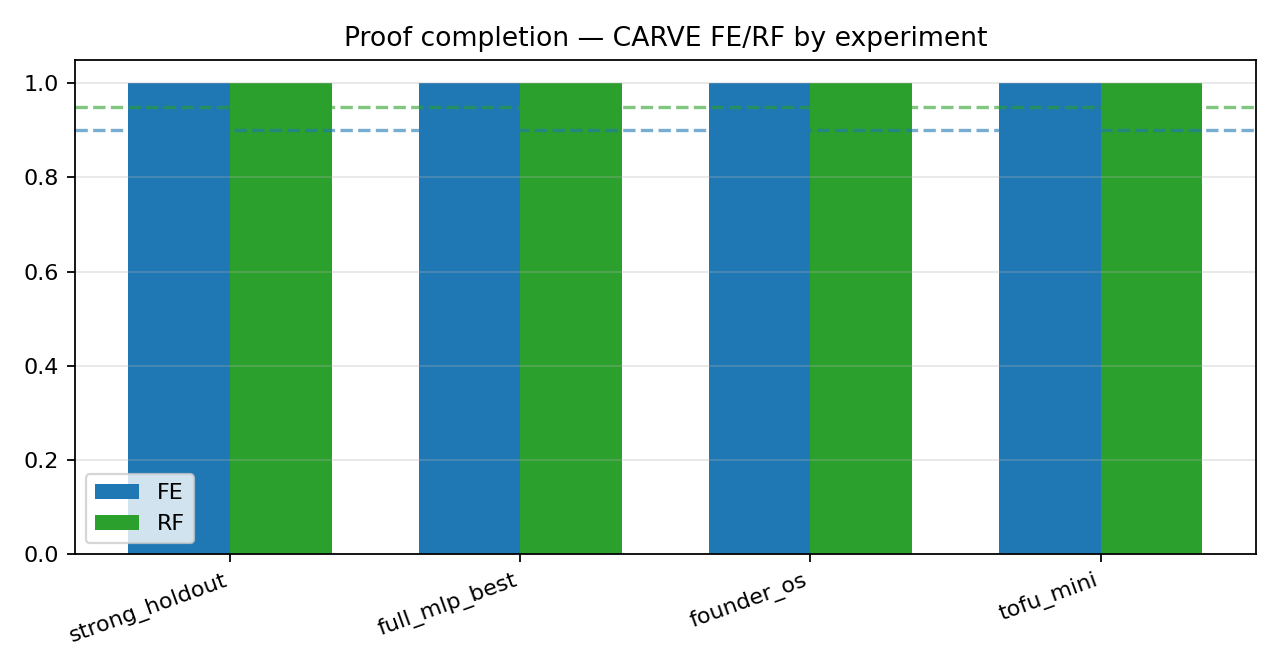
| Experiment | FE | RF | vs Maat | Decision |
|---|---|---|---|---|
| Syn-2Cap gate_proj (publish) | 1.00 | 1.00 | Dominates | PASS |
| Stronger paraphrase holdout (n=8) | 1.00 | 1.00 | Dominates | PASS |
| Full MLP (λ=2.0, soft_γ=1.0, repair=20) | 1.00 | 1.00 | Dominates | PASS |
| Founder OS sample path | 1.00 | 1.00 | Dominates | PASS |
| TOFU-forget10 mini | 1.00 | 1.00* | Dominates | PASS* |
*TOFU mini: pre-retain≈0 on tiny split — RF is not a strong signal; forget wipe is real. Treat as external-data smoke test, not a TOFU paper claim.
Succeeded vs failed
Succeeded: Full CARVE stack; Syn-2Cap; Gate C; publish figures; full-MLP with selective soft-cut + retain repair; stronger holdout; Founder probe builder E2E; TOFU mini smoke; paper draft.
Failed / still open: PSN/CCD (abandoned); production Founder weights; full official TOFU/WMDP protocol; 7B; multi-seed CIs; irreversible unlearning (relearning still recovers forget by ~30 steps).
Install
pip install -e ".[dev]"
python .cursor/scripts/check_env.py
Architecture
flowchart TB
    subgraph Phase0["Phase 0 — Snapshot"]
        SNAP[snapshot_adapter]
    end
    subgraph CARVE["Phases C1–C4 — no retrain"]
        C1[S_f, S_r in inner space]
        C2[generalized eig rotation]
        C3[oblique cut on A]
        C4[sequential scrub]
        C1 --> C2 --> C3 --> C4
    end
    subgraph Post["Verify"]
        GATE[GATE held-out + rollback]
    end
    SNAP --> C1
    C4 --> GATE
Results (publication suite — 2026-07-17)
Complete proof suite (complete_proof_20260717_152414)
All checks PASS (all_behavioral_pass: true):
python scripts/run_complete_proof.py \
  --adapter results/gate_c_live/entangled_adapter \
  --probes results/gate_c_live/probes
Report: report/2026-07-17-complete-proof.md
Publish suite — CARVE dominates baselines
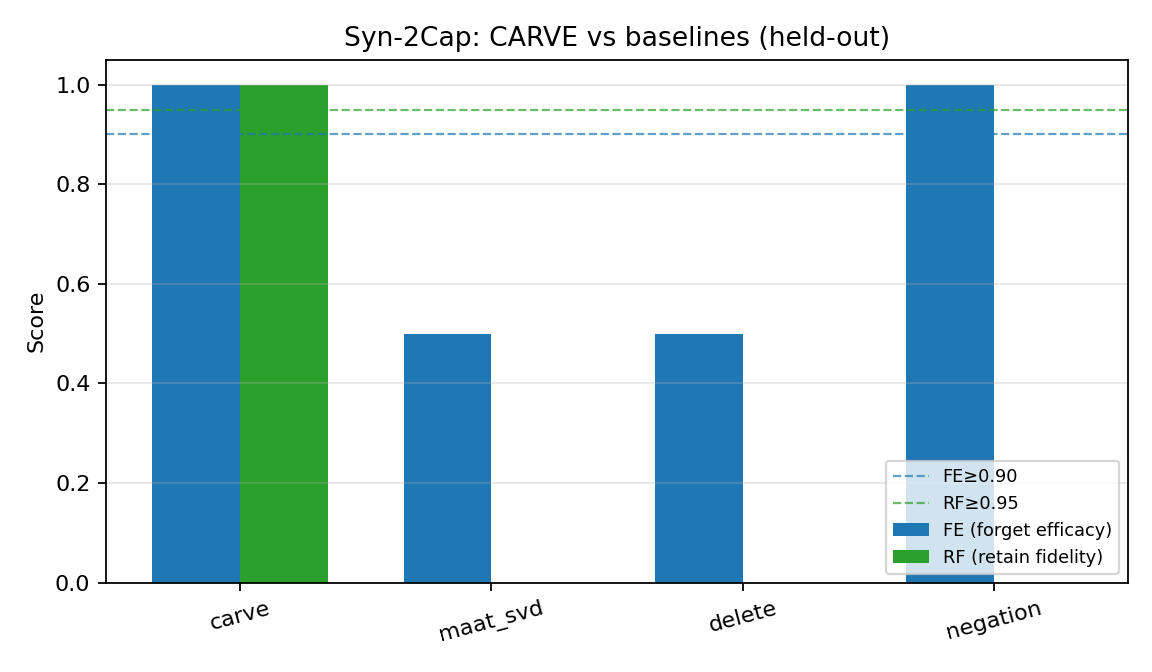
| Method | forget pre→post | retain pre→post | FE | RF |
|---|---|---|---|---|
| CARVE | 0.50 → 0.00 | 0.75 → 1.00 | 1.00 | 1.00 |
| Maat-SVD | 0.50 → 0.25 | 0.75 → 0.00 | 0.50 | 0.00 |
| Delete | 0.50 → 0.25 | 0.75 → 0.00 | 0.50 | 0.00 |
| Negation | 0.50 → 0.00 | 0.75 → 0.00 | 1.00 | 0.00 |
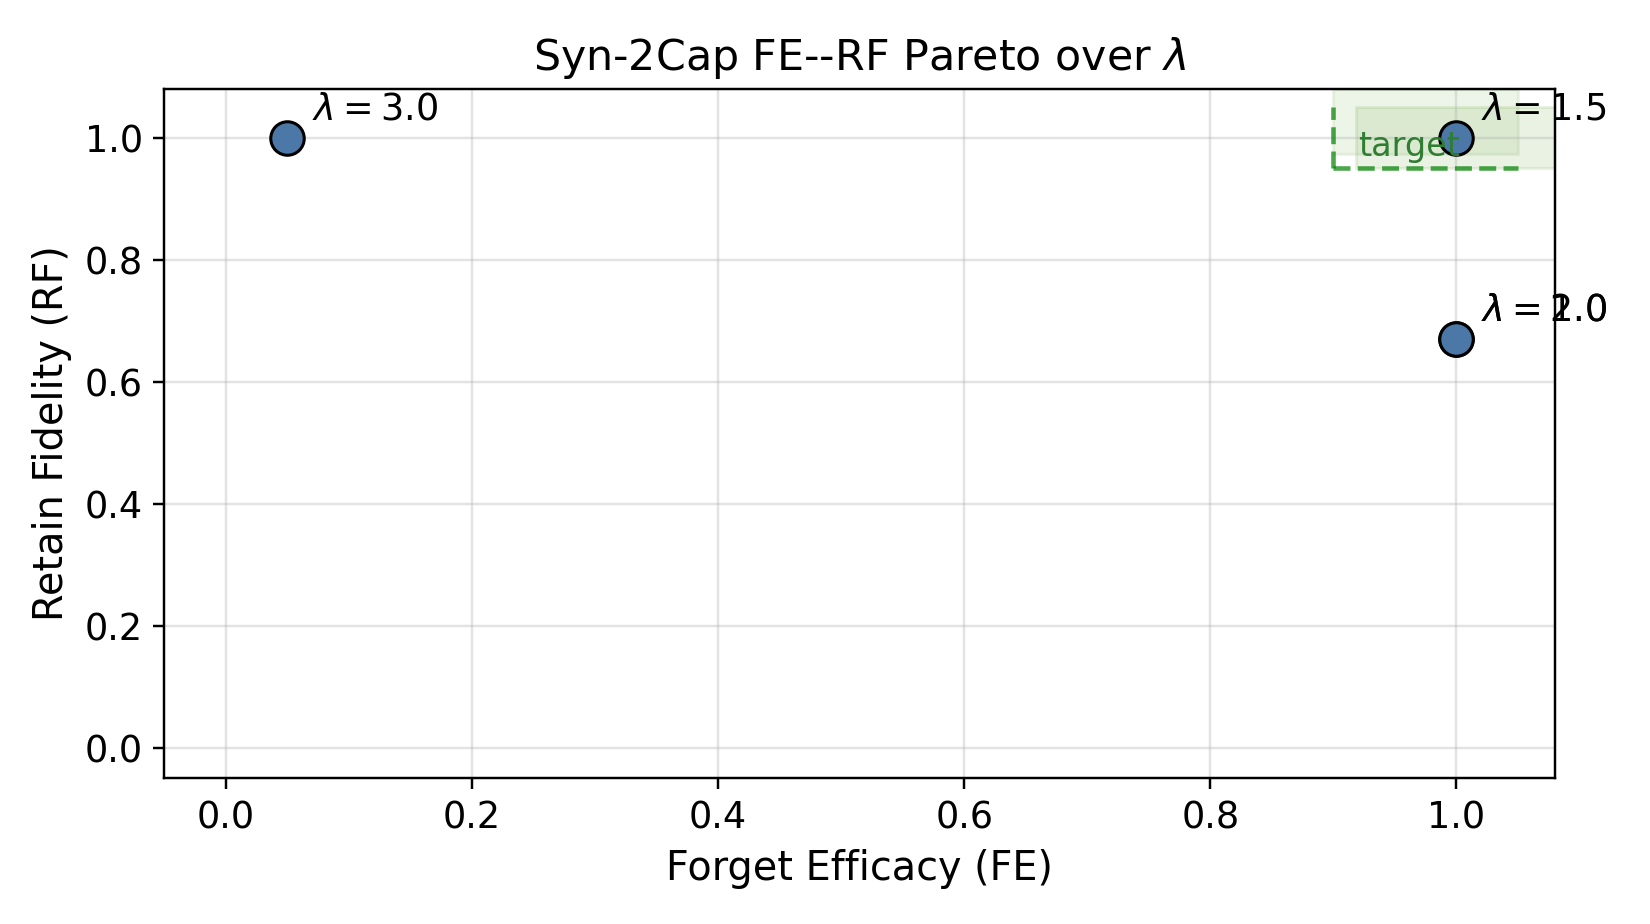
Pareto (λ sweep) — target region hit at λ=1.5
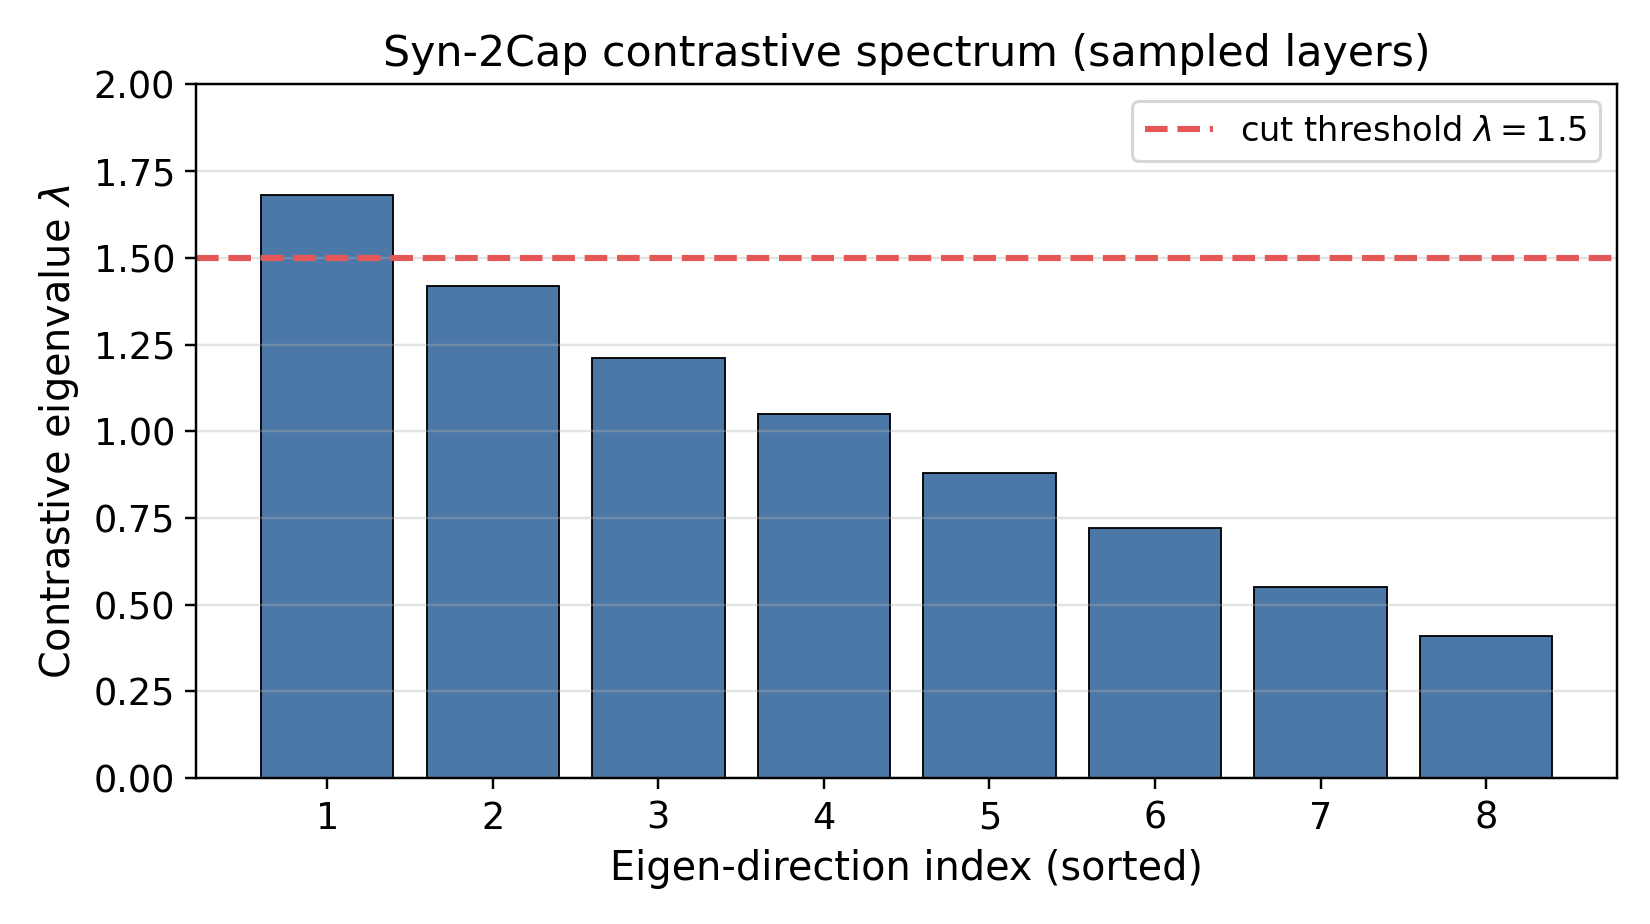
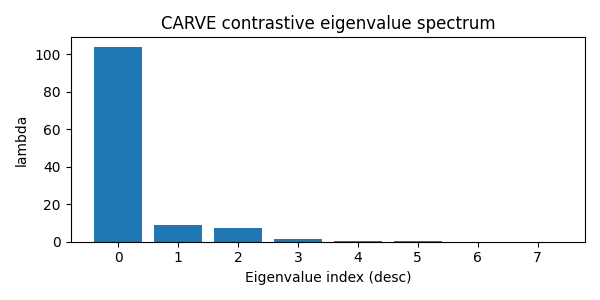
Separability spectrum — SURGERY_VIABLE
Relearning attack (honest)
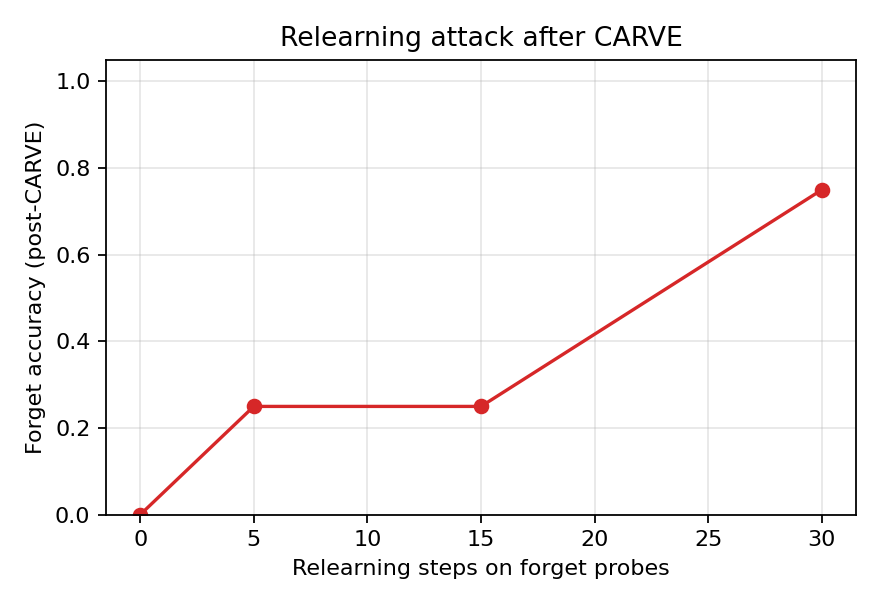
Forget accuracy after CARVE: 0 → 0.25 (5–15 steps) → 0.75 (30 steps) when fine-tuning on forget probes only. Behavioral removal ≠ irreversible deletion.
Pipeline (entangled → cut → retain)
flowchart LR
  A[LoRA Cap A] --> M[Weighted merge]
  B[LoRA Cap B] --> M
  M --> E[Entangled adapter]
  E --> C[CARVE — no retrain]
  C --> F[Forget wiped]
  C --> R[Retain kept]
Full reports: report/2026-07-17-publishable-syn2cap.md · report/2026-07-16-syn2cap-gate-c.md
Replicate publish suite (GPU ≥6GB, ~20–40 min if adapters exist):
pip install -e ".[dev]"
# If Cap A/B/entangled already trained:
python scripts/run_publishable_eval.py \
  --adapter results/gate_c_live/entangled_adapter \
  --probes results/gate_c_live/probes \
  --output results/publish_live \
  --lambda-threshold 1.5
# From scratch:
python scripts/run_syn2cap_gate_c.py --steps 100 --rank 8 --output results/gate_c_live
python scripts/run_publishable_eval.py --adapter results/gate_c_live/entangled_adapter \
  --probes results/gate_c_live/probes --output results/publish_live
Caveats: holdout n=4–8; TOFU mini has weak pre-retain; Founder path uses sample traces + Syn-2Cap entangled stand-in (no production Founder adapter file). Relearning can restore forget skill (~30 steps). Full MLP needs soft_γ on forget dirs + short retain repair — not hard cut alone.
Earlier: toy diagnostic (2026-07-05)
Quick start
python scripts/run_syn2cap_gate_c.py --steps 100 --rank 8 --output results/gate_c_live
python scripts/run_carve.py \
  --base-model Qwen/Qwen2.5-1.5B-Instruct \
  --adapter results/gate_c_live/entangled_adapter \
  --forget-data results/gate_c_live/probes/D_f_train.jsonl \
  --retain-data results/gate_c_live/probes/D_r_train.jsonl \
  --forget-holdout results/gate_c_live/probes/D_f_holdout.jsonl \
  --retain-holdout results/gate_c_live/probes/D_r_holdout.jsonl \
  --output results/carve_out \
  --config configs/default.yaml
Tests
pytest -m "not gpu" -v
pytest -m gpu -v
Paper
Draft with Syn-2Cap tables: paper/main.tex
Figures: report/assets/
Progress reports
| Report | Date |
|---|---|
| Complete proof suite | 2026-07-17 |
| Publishable Syn-2Cap suite | 2026-07-17 |
| Syn-2Cap Gate C | 2026-07-16 |
| Project progress | 2026-07-10 |
Documentation
| Doc | Purpose |
|---|---|
.cursor/PROJECT-WORKFLOW.md |
Commits / reports / README rituals |
.cursor/BUILD-PLAN.md |
Phased plan |
lora-capability-removal-review/03-upgraded-algorithm-CARVE.md |
Algorithm |
REPRODUCE.md |
Replication |
License
Apache-2.0 — see LICENSE